
How to Document APIs in Confluence
Short answer: Give the API its own space with four sections: Getting Started (authentication, rate limits, SDKs), an API Reference with one page per endpoint, a Changelog and Guides. Each endpoint page lists the method, path, parameters, an example request and response, and error codes. Keep the generated OpenAPI spec for the schema and use Confluence for the context it can't carry.
API docs fail for the same reasons every time: they live in too many places, nobody owns them, and updating them feels optional.
The Postman collection is the real reference. The Swagger file is six months behind the code. The Confluence page was accurate once. The README has a curl example that stopped working in v2. Developers new to the codebase have to triangulate between all of them and ask a colleague anyway.
Centralizing API documentation in Confluence doesn't fix all of this automatically, but it gives you a single place to link from everywhere else, and the right structure makes it far easier to keep up to date.
Why API Documentation Gets Stale
The core problem isn't that people are lazy. It's that documentation lives in a different tool than the code, so every change requires two actions: update the code, then update the docs. That second step gets skipped when deadlines are tight, and it never catches up.
Secondary problems layer on top:
- No clear owner. The developer who built it moves on. Nobody else knows enough to update it confidently.
- Wrong format. Prose descriptions of request bodies are ambiguous. Code examples with no explanation assume too much. A mix of both with no consistent structure is the worst of both worlds.
- Swagger/OpenAPI as the only source. Generated docs show what the API does, not why, what the gotchas are, or how it behaves in production edge cases.
Good API documentation combines auto-generated spec output with hand-written context. Confluence is where the hand-written context should live.
What Good API Documentation Includes
For each API (or logical group of endpoints), your documentation should cover:
Authentication and authorization: how to get credentials, token lifetime, scope requirements, which endpoints need which permissions. This is the most-asked question from new integrators and the hardest to find in auto-generated docs.
Base URL and versioning: current version, how versioning works, deprecation policy. A table showing v1/v2 differences is worth more than a paragraph.
Endpoint reference: for each endpoint: method, path, description, request parameters (path, query, header, body), example request, example response, error codes. See the template at the bottom of this post.
Error codes: a dedicated table of all error codes, what they mean, and what the caller should do about them. 400 Bad Request is not useful documentation.
Changelog: what changed between versions and when. The changelog is the first thing an existing integrator checks when something breaks after a release.
Rate limits and quotas: numbers, what triggers throttling, what the response looks like, how to handle retry.
Structuring API Docs in Confluence
A Confluence space structure that works well for a team maintaining one or more APIs:
API Documentation (space root)
├── Getting Started
│   ├── Authentication
│   ├── Rate Limits & Quotas
│   └── SDKs & Client Libraries
├── API Reference
│   ├── Users API
│   │   ├── GET /users
│   │   ├── POST /users
│   │   ├── GET /users/{id}
│   │   └── DELETE /users/{id}
│   └── Orders API
│       └── ...
├── Changelog
│   ├── v3.0.0 (2026-04-01)
│   ├── v2.5.0 (2025-12-10)
│   └── ...
└── Guides
    ├── Handling Pagination
    ├── Webhook Setup
    └── Error Handling Patterns
Keep the API Reference section flat within each API group, with one page per endpoint. Deep nesting makes the sidebar useless. The Changelog and Guides sections are where you write prose; the Reference section is where you write specs.
Writing Request and Response Examples in Confluence
This is where most Confluence API docs fall apart. People write prose descriptions of JSON fields, or paste unformatted request examples that are impossible to scan.
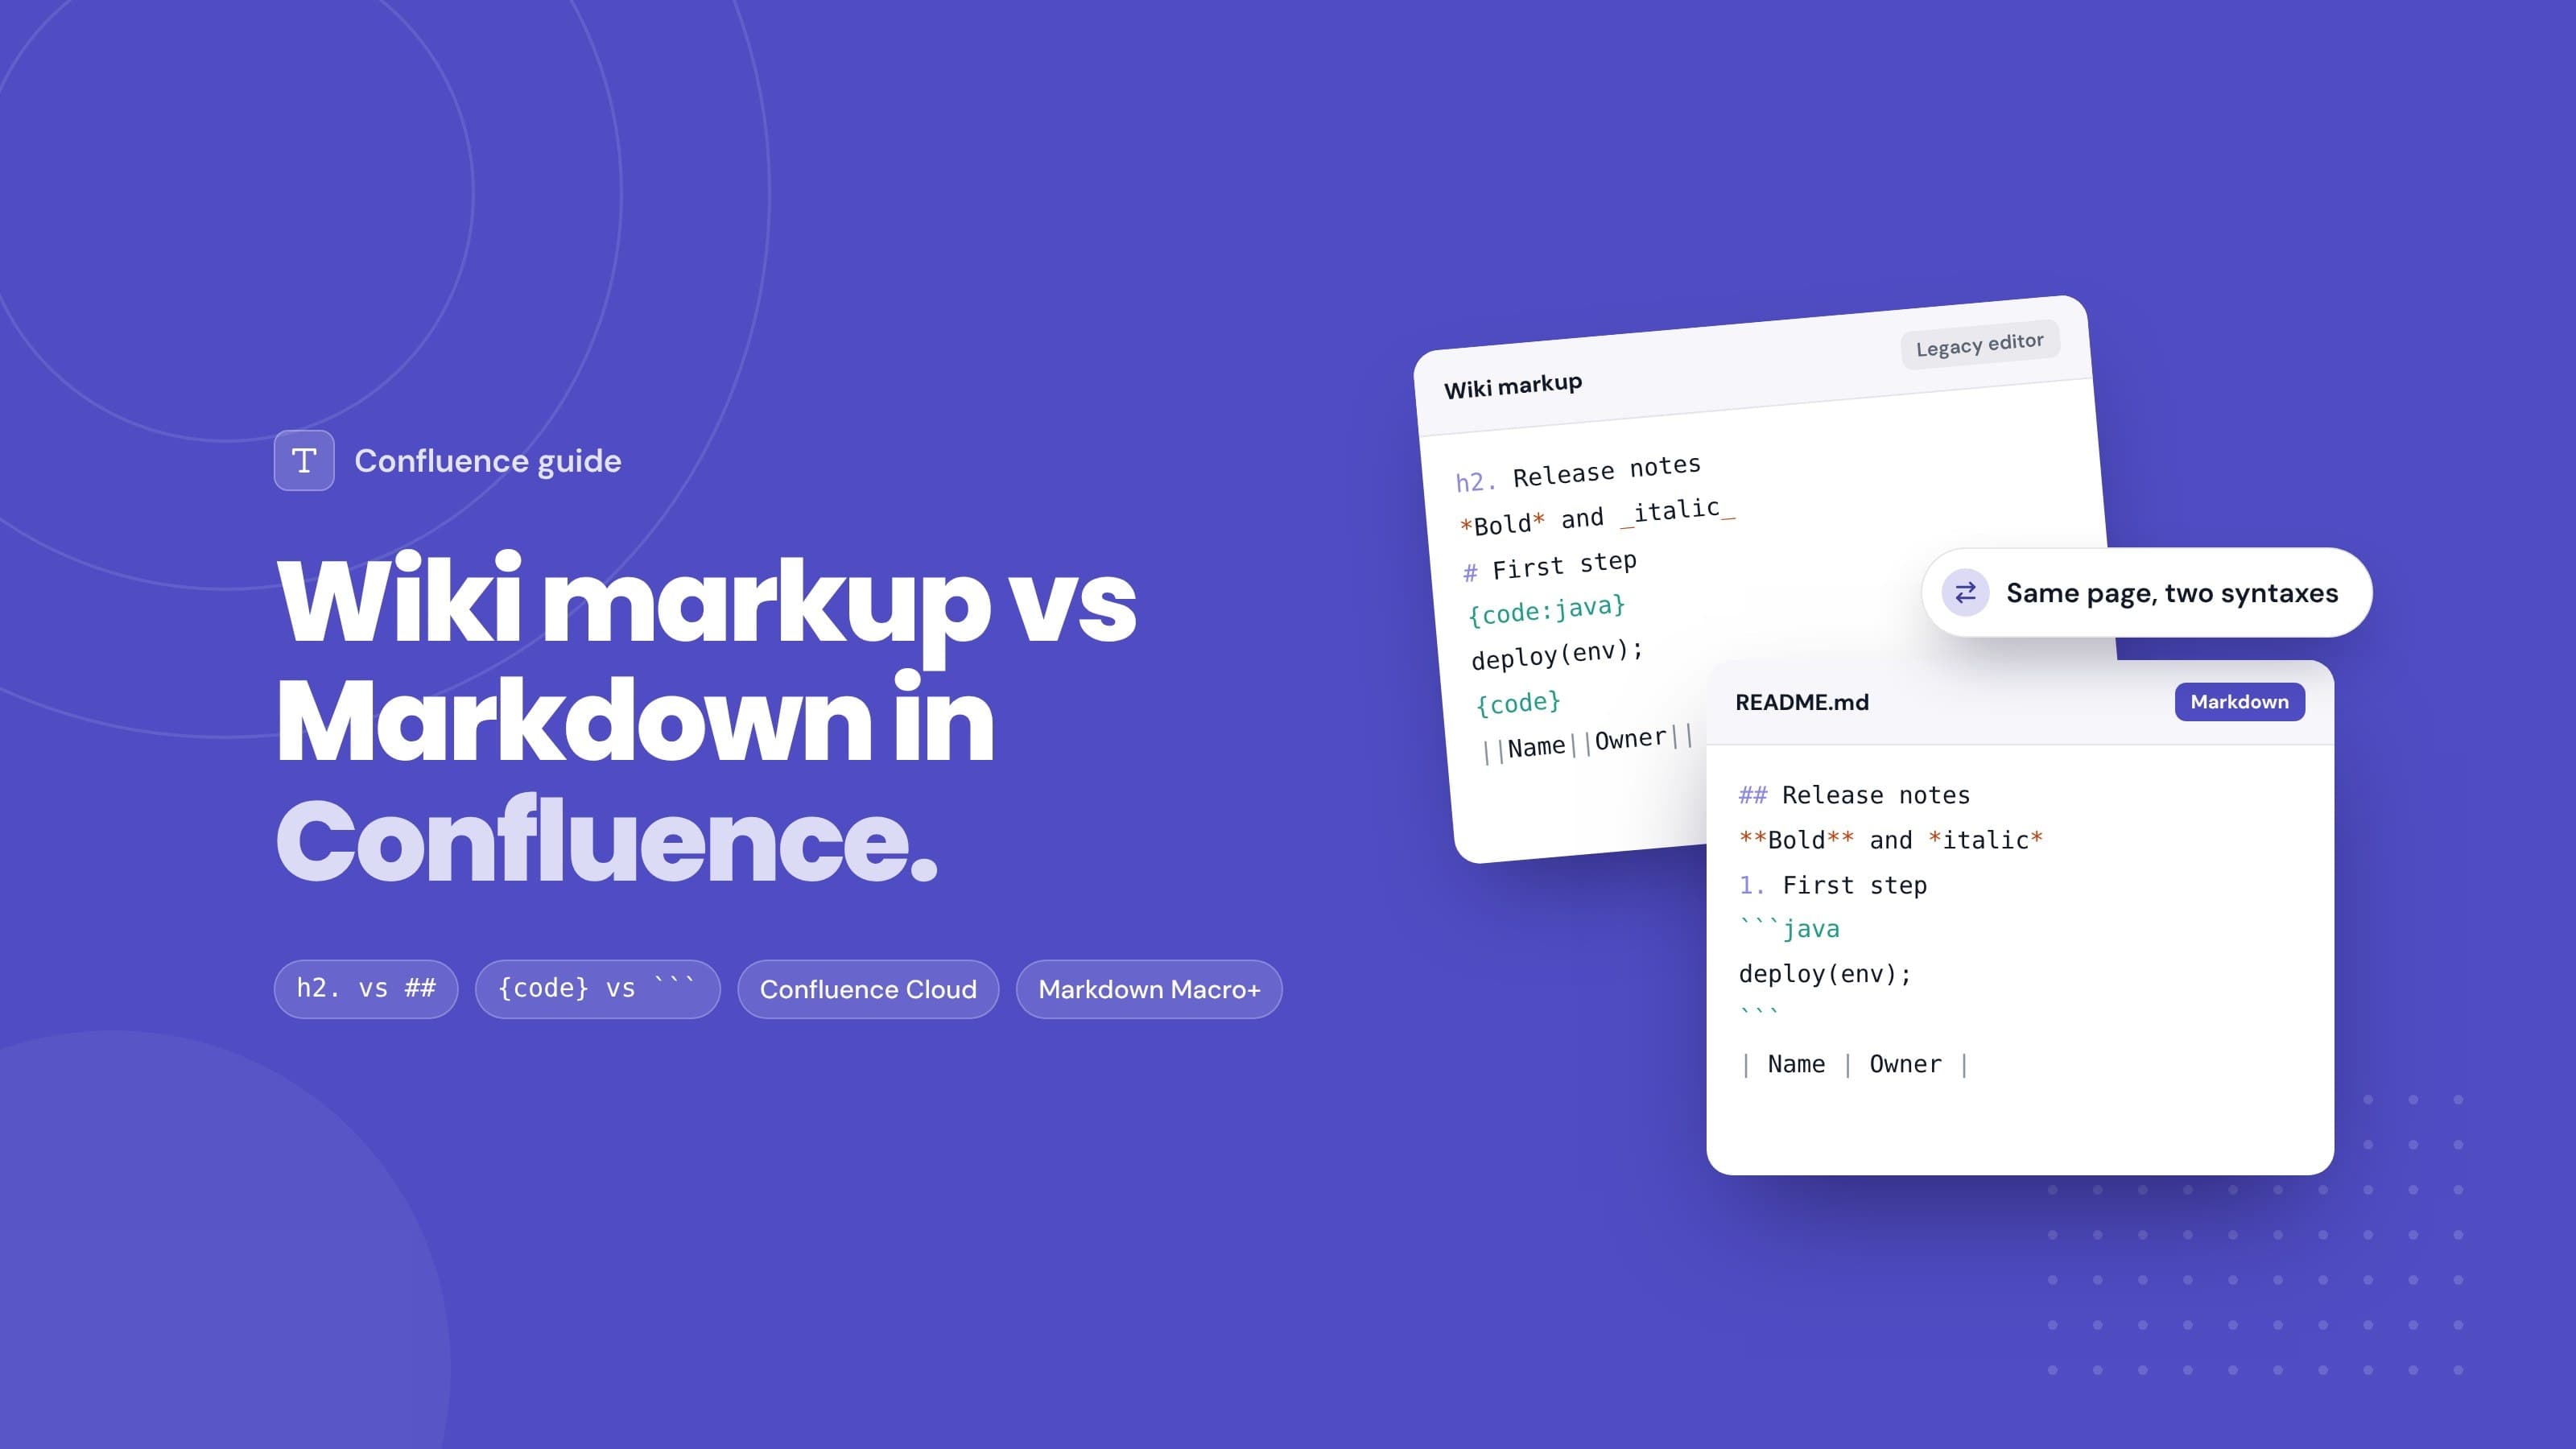
The right approach is structured code blocks with clear labels. Markdown Macro+ for Confluence lets you write these directly in markdown on any Confluence page, including fenced code blocks with language hints that render with syntax highlighting. If you stick with the native editor, here is how to add code blocks in Confluence.
A request example written in markdown on a Confluence page:
**Request**

```http
POST /v3/orders
Authorization: Bearer {token}
Content-Type: application/json

{
  "customer_id": "cus_8f3k2",
  "items": [
    { "sku": "WIDGET-001", "quantity": 2 },
    { "sku": "GADGET-042", "quantity": 1 }
  ],
  "shipping_address": {
    "line1": "123 Main St",
    "city": "Austin",
    "state": "TX",
    "zip": "78701"
  }
}
```

**Response: 201 Created**

```json
{
  "order_id": "ord_9g4m1",
  "status": "pending",
  "created_at": "2026-05-20T14:32:00Z",
  "total_cents": 4799
}
```
This renders cleanly in Confluence with the Markdown Macro, and it's easy to edit. No hunting for macros and no storage format XML, just markdown.
Keeping Docs in Sync with Code
The documentation drift problem doesn't go away with better structure. It needs a process fix too.
Link the Confluence page from the code. Add a comment in the route handler or controller pointing to the Confluence page. When a developer changes the endpoint, the link is right there.
# POST /v3/orders
# Docs: https://yourspace.atlassian.net/wiki/x/AbCdEf
@app.route("/v3/orders", methods=["POST"])
def create_order():
    ...
Add the docs update to your PR checklist. If your team uses a PR template, add a checkbox: "Updated API docs in Confluence if endpoints changed." It sounds obvious but it works.
Publish from CI. For docs-as-code teams, the most reliable fix is to keep the reference pages as markdown in the same repo as the code and publish them on every merge. Two options:
-
Markdown Importer REST API. Markdown Importer for Confluence has a REST API that takes markdown and creates or updates a Confluence page, so your pipeline doesn't have to convert anything to Confluence's storage format. Our guide on syncing GitHub docs to Confluence automatically has a complete GitHub Actions setup, and the API examples cover GitLab CI too.
-
Confluence REST API directly. If you'd rather render pages yourself (for example from an OpenAPI spec), use the Confluence Cloud REST API v2. With a personal API token, authenticate with Basic auth using your Atlassian account email and the token. To update a page, send the next version number along with the full body in storage format:
# Update a Confluence Cloud page (REST API v2)
curl -X PUT \
  "https://yoursite.atlassian.net/wiki/api/v2/pages/{pageId}" \
  -u "[email protected]:$CONFLUENCE_API_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
    "id": "{pageId}",
    "status": "current",
    "title": "GET /users/{id}",
    "body": {
      "representation": "storage",
      "value": "<p>Updated content here</p>"
    },
    "version": {
      "number": 12,
      "message": "Updated from CI"
    }
  }'
The version number must be one higher than the page's current version, so fetch the page first (GET /wiki/api/v2/pages/{pageId}) and increment it. Atlassian's Basic auth guide and the v2 page API reference have the details.
Either way, keep generated reference pages separate from hand-written context pages so a CI run never overwrites the prose.
Page Template: API Endpoint Reference
Here's a practical template for a single endpoint page. Copy it, fill it in, repeat per endpoint.
## Overview

Brief description of what this endpoint does and when to use it.

## Request

**Method & Path:** `POST /v3/users`

**Authentication:** Bearer token required. Scope: `users:write`

### Headers

| Header | Required | Description |
|--------|----------|-------------|
| `Authorization` | Yes | `Bearer {token}` |
| `Content-Type` | Yes | `application/json` |

### Body Parameters

| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `email` | string | Yes | User's email address |
| `name` | string | Yes | Display name |
| `role` | string | No | One of: `admin`, `member`, `viewer`. Default: `member` |

### Example Request

```http
POST /v3/users
Authorization: Bearer eyJhb...
Content-Type: application/json

{
  "email": "[email protected]",
  "name": "Alex Kim",
  "role": "member"
}
```

## Response

### 201 Created

```json
{
  "user_id": "usr_7c2p9",
  "email": "[email protected]",
  "name": "Alex Kim",
  "role": "member",
  "created_at": "2026-05-20T10:00:00Z"
}
```

## Error Codes

| Code | Meaning | Action |
|------|---------|--------|
| `400` | Missing required field | Check request body against schema |
| `409` | Email already registered | Use existing account or change email |
| `422` | Invalid role value | Use one of: admin, member, viewer |
| `429` | Rate limit exceeded | Back off and retry after `Retry-After` header |

## Notes

Any gotchas, rate limit specifics, or behavior that differs from the general rules.
Getting Started
Install Markdown Macro+ for Confluence from the Atlassian Marketplace to write and edit API docs in markdown directly on Confluence pages, with code blocks and tables. If your API docs already live as markdown in a repo, Markdown Importer for Confluence can bring them in, once or from CI.
For the wider engineering wiki around your API docs, see how to use Confluence as a developer wiki.
Questions? Reach out via our support portal.